Systems | Development | Analytics | API | Testing

ETL Pipeline: What It Is, How to Build One & Best Practices

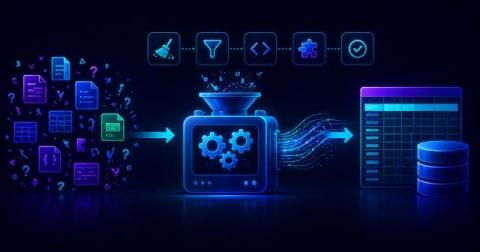
An ETL pipeline is a set of processes and tools that enables businesses to extract raw data from multiple source systems, transform it to fit their needs, and load it into a destination system for various data-driven initiatives. ETL pipelines are a specific type of data pipeline, and the systems they feed are typically databases, data warehouses, or data lakes.
Do You Really Need a Data Vault?

Data Vault 2.0 modeling methodology has gained immense popularity since its launch in 2013. It’s a hybrid model that combines the benefits of Third Normal Form (3NF) and star schema architectures, making it a dream solution for data warehousing engineers. But is it worth implementing for your data warehouse architecture? The answer isn’t straightforward, as there are many factors to consider. So, let’s dive in and explore whether Data Vault 2.0 is right for you.

Simplifying PDF Data Extraction with ReportMiner 10.0

IDC estimates that 80% of data generated and collected by organizations is unstructured, i.e., stored in a format that is not easily extractable. PDFs are among the most widely used unstructured file formats for storing and exchanging business information. Despite the extensive usage of PDFs, content stored in them is not machine-readable, hence cannot be easily extracted and organized into rows and tables. So, how can enterprises overcome the problem of PDF data extraction?

Should you Build or Buy Your Data Parsing Tool?

Before we dive deeper into data parsing tools, we must understand what parsing means. Consider the following sentence: The adept software parsed the problematic data. Intuitively, we all understand what this means, but what if we broke it down into a simpler format? The process of dividing this sentence into its subject, verb, and object is known as linguistic parsing. By performing linguistic parsing, readers can better understand the intention behind an author’s words.

Parquet to CSV Conversion Guide

When you’re managing very large datasets, you know that data comes in many formats. Fortunately, the modern-day data landscape has led to the evolution of file formats that allow faster data processing and ensure reduced time to market. The recent introduction in the realm of file formats is Parquet, which can handle large volumes of complex data more efficiently. You might be working with several Parquet files because of their efficiency in storing and processing analytical data.

What is Data Munging and Why is it Important? A Complete Guide

Data munging is the process of preparing raw data for reporting and analysis. It incorporates all the stages prior to analysis, including data structuring, cleaning, enrichment, and validation. The process also involves data transformation, such as normalizing datasets to create one-to-many mappings. It is also known as data wrangling.

Best PDF Data Extraction Software in 2026: 9 Tools Compared

PDF data extraction software, also called PDF extraction software or a PDF extractor, automatically pulls text, tables, and fields out of PDF files and converts them into structured data you can use in spreadsheets, databases, and business applications. A PDF extraction software can help you convert unstructured data in PDF files to clean, structured data that can be stored in a data warehouse for reporting and business intelligence.

Build an HR Data Warehouse for Effective Payroll Analysis

The modern employee demands a working culture that delivers flexibility, work-life balance, ongoing professional development, a strong sense of purpose, and most importantly, fair compensation. If these requirements aren’t met, they’re more willing than ever to switch jobs and find opportunities aligned with their personal objectives. Therefore, building and maintaining an HR Data Warehouse for payroll analysis is crucial for managers to keep a historical record of financial data.