Systems | Development | Analytics | API | Testing

Replication in Apache Kafka Explained | Monitoring & Troubleshooting Data Streaming Applications

Learn how replication works in Apache Kafka. Deep dive into its critical aspects, including: Whether you're a systems architect, developer, or just curious about Kafka, this video provides valuable insights and hands-on examples. Don't forget to check out our GitHub repo to get all of the code used in the demo, and to contribute your own enhancements.
Preparing the Consumer Fetch: Kafka Producer and Consumer Internals, Part 3

Welcome back to the third installment of our blog series where we’re diving into the beautiful black box that is Apache Kafka to better understand how we interact with the cluster through producer and consumer clients. Earlier in the series, we took a look at the Kafka producer to see how the client works before following a produce request as it’s processed by the cluster.

How Booking.com Used Data Streaming to Put Travel Decisions into Customer's Hands

Booking.com wanted to give people a “connected trip” experience, allowing customers to seamlessly book flights, accommodations, car rentals, and excursions in one visit. The company realized the value of data streaming early on in reaching this goal, but the operational effort had become overwhelming. Learn how Booking.com found the answer in Confluent’s data streaming platform. With its automated configuration that required no ongoing maintenance, the team was able to prioritize innovation with data and provide the comprehensive booking experience they had been searching for.

How to source data from AWS DynamoDB to Confluent using the Open-Source Connector

This is a one-minute video showing an animated architectural diagram of an integration between Amazon DynamoDB and Confluent Cloud using an open-source Kafka connector. The integration allows you to avoid maintaining custom code, and gives you the ability to automatically discover and adapt to changes in DynamoDB tables. All details are provided.

Handling the Producer Request: Kafka Producer and Consumer Internals, Part 2

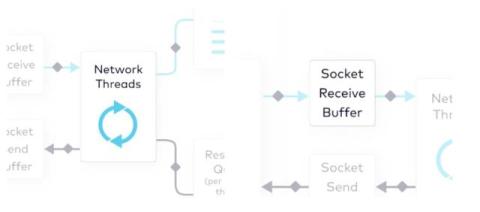
Welcome to the second installment of our blog series to understand the inner workings of the beautiful black box that is Apache Kafka. We’re diving headfirst into Kafka to see how we actually interact with the cluster through producers and consumers. Along the way, we explore the configurations that affect each step of this epic journey and the metrics that we can use to more effectively monitor the process.