Katalon AI Test Execution and False Passes
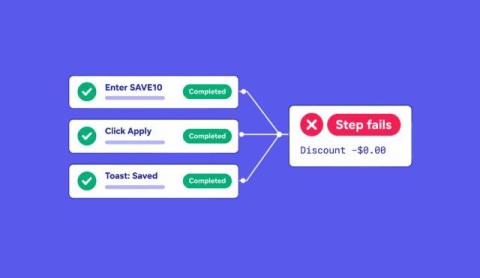
In a release test I published in July, Katalon’s AI runner reported seven cases passed and four failed. I could open the steps, inspect their screenshots, and watch the browser session. The failed rows showed which expectations broke. The passed rows deserve the same scrutiny: what had the agent observed before it called each step passed? An AI test runner has to perform the action and judge the outcome. A false pass is a passed verdict when the expected behavior did not occur.