Systems | Development | Analytics | API | Testing

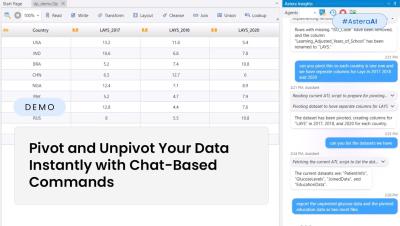
Pivot and Unpivot Your Data Instantly with Chat-Based Commands

The fastest way to prep your data is here. With Astera’s AI-driven Data Prep, you can simply chat your way to clean, structured data. No clicks or complicated steps. Just tell the data what you need. Watch how effortlessly you can reshape your data, whether it’s unpivoting for easy filtering or pivoting for reports and dashboards.
Introducing KIP-848: The Next Generation of the Consumer Rebalance Protocol

The consumer group is a cornerstone of Apache Kafka, enabling scalable and fault-tolerant data consumption by allowing multiple consumer instances to share the workload of reading from topic partitions. The consumer rebalance protocol is the mechanism that coordinates which partitions are assigned to which consumers within a group.

Leveraging Cortex AISQL For Multi-Modal Analytics

Snowflake's Senior Product Manager Renee Huang demonstrates how to leverage Snowflake's powerful Cortex AISQL functions for advanced analytics on unstructured and structured data. Her demonstration includes a look at how to use functions such as AI_AGG, AI_CLASSIFY, AI_COMPLETE, and AI_FILTER on your data to accelerate insights. For more information, check out this blog post.

Talk To Your Data: Snowflake Intelligence Demo

Unlock instant insights from ALL your data using agentic AI. In this demo, Snowflake's Director of Product Management Jeff Hollan shows how Snowflake Intelligence lets anyone in your enterprise use natural language to talk to data – structured, unstructured, and external. See how agents help you understand what happened and why, and even enable you to take action. Transform your data experience with Snowflake Intelligence. Easy, Connected, Trusted.

Pipeline Data for Fueling Analytics, & Business Strategy

In modern data architecture, it’s tempting to focus on flashy dashboards, real-time data AI models, or the scalability of cloud warehouses. But these are only as good as the fuel behind them: pipeline data. This post unpacks what pipeline data really is, why it matters, how it moves through your architecture, and what to do to protect and optimize its value.

Data Integration Architecture: Blueprint for Insights

In today’s fragmented and high-velocity data environment, data integration architecture is not just a technical framework—it’s a strategic imperative. As businesses increasingly rely on insights drawn from multiple systems, the need for a robust and scalable architecture that governs how data is collected, processed, and delivered has never been greater.

The 5 Levels of Data User Sophistication We See in the Market

At Integrate.io, we work with hundreds of companies, primarily midmarket and enterprise organizations ranging from agile RevOps teams to global enterprises with complex, multisource data ecosystems. Across these engagements, we’ve noticed something consistent: the way people work with data tends to fall into a handful of distinct, predictable levels. It’s not about company size, tech stack, or vertical.

Introducing the Agentic Semantic Layer: A New Standard for Data Foundations

For data analysts and engineers, the journey from raw data to actionable business insights for business users is never as simple as it sounds. The semantic layer is a critical component in this process, serving as the bridge between complex data sources and the business logic required for informed decision-making. However, not all semantic layers are created equal, and the evolving landscape of AI-powered analytics demands a new approach.