Systems | Development | Analytics | API | Testing

WSO2 AI Guardrails: PII Masking, Prompt Injection & Safety

Generative AI offers incredible potential, but it comes with real risks like data leakage and prompt attacks. In this video, we demonstrate how WSO2 AI Guardrails act as an intelligent filter to secure your AI integrations and ensure compliance. We walk through the configuration of four critical advanced guardrails to inspect both incoming requests and outgoing responses, helping you move from risky experiments to safe, reliable production services.
WSO2 AI Gateway: Prompt Management & Semantic Caching

Learn how to ensure consistent AI interactions and drastically reduce latency using the WSO2 AI Gateway. This step-by-step tutorial demonstrates how to standardize your LLM requests for quality and efficiency while cutting down on redundant API costs. We explore "Prompt Management" to enforce organizational guidelines using templates and decorators, and "Semantic Caching" to leverage vector embeddings—serving instant, cached responses for semantically similar queries to minimize expensive LLM calls.

How AI Is Redefining Route Optimization to Enable Faster Deliveries?

When executives talk about improving logistics performance, the conversation often circles around the same three goals: speed, cost efficiency, and reliability. Yet the reality on the ground tells a different story. Traffic congestion, rising fuel costs, driver shortages, changing customer expectations, and unpredictable disruptions continue to make route planning one of the most complex operational challenges in logistics. Now add one more pressure point: customer expectations have fundamentally changed.

The Breakdown | API calls and mobile apps

You used an API this morning. Probably before you even got out of bed. That weather app? It's your phone communicating with a server in the cloud — sending a request, getting data back, and displaying it on your screen in seconds. Location. Request format. Expected response. That's the anatomy of an API call. And it's happening constantly across nearly every app on your phone. Hugo Guerrero and Amanda Alcamo break it all down in Episode 2 of The API & AI Breakdown. No jargon. No fluff. Just clarity.

Ship React Native updates in minutes: CodePush on Bitrise is now live

React Native teams ship fast. App store reviews do not. Today, CodePush officially launched on Bitrise, giving React Native teams the ability to deliver JavaScript and asset updates directly to users in minutes, without waiting for App Store or Play Store approval.

AI Input vs. Output: Why Token Direction Matters for AI Cost Management

In the burgeoning intelligence economy, AI tokens are a metered utility, but enterprise profitability now hinges on a critical distinction: output tokens can cost up to 10x more than inputs, creating a new, invisible risk for cost overruns, particularly with Agentic AI. Learn how Kong AI Gateway and Konnect Metering & Billing provide the essential financial control plane to enforce directional guardrails, protect margins, and turn token consumption into realized revenue.

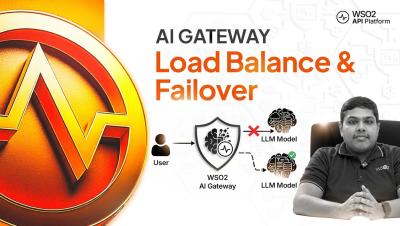
Stop GenAI Rate Limits: Model Routing & Token Throttling with WSO2 AI Gateway

Learn how to mitigate skyrocketing AI costs and prevent model outages using the WSO2 AI Gateway. This step-by-step tutorial shows you how to move beyond simple request limits and implement smart, token-based usage policies. We also demonstrate "Adaptive Model Routing" showing you how to automatically switch between models when rate limits are hit, and how to distribute traffic using weighted round-robin to optimize for cost and performance.