Systems | Development | Analytics | API | Testing

Signal Over Noise: Building an Intentional Al Workflow That Scales

AI writes code faster than any team can check it. Diego Molina thought he had a tooling problem. He didn't. In 37 minutes he shows the workflow mistake most engineering teams are making right now, the one bottleneck that decides whether AI speeds you up or buries you, and the principles that drive his own workflow scale without the noise. Chapters Learn more at saucelabs.com.
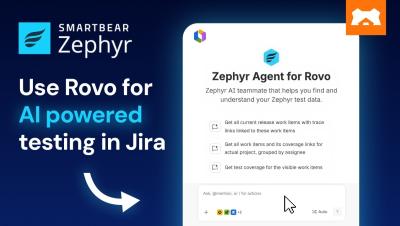
How to use Rovo for AI-powered testing in Jira | SmartBear Zephyr Agent for Rovo

Rovo, Atlassian’s AI assistant, can help you generate test cases directly inside Jira through the SmartBear Zephyr Agent for Rovo. This demo offers a practical look at AI-powered testing with Rovo in Jira, from requirements to reviewed test cases, all within the Jira experience, without switching tools.

Ep 91 | Beyond the POC: AWS's Playbook for Enterprise AI Success

Most AI pilots never make it past the demo phase. AWS Machine Learning Lead Praveen Jayakumar has seen plenty of promising AI projects get stuck between a successful demo and production. Teams often define what success looks like without deciding what failure looks like, leaving underperforming projects alive long after they should have been shut down. As Praveen puts it, they become “zombie” AI projects.

What is LLM Context Windows & Context Engineering? Explained by Toni Ramchandani

This session takes a practical look inside LLM context windows and token consumption, exploring what happens when context enters a model - from tokenization, embeddings, attention, QKV, prefill, and decode to KV caching. It also examines how context windows are allocated and why simply increasing context length doesn’t always lead to better model performance.

Your GitHub Actions cache is the real bottleneck

Namespace, Avrea, and Blacksmith are among the fastest GitHub Actions runner providers on the market right now. According to Avrea's August 2026 benchmarks, they all score within about 1% of each other on raw CPU. The same benchmark shows warm builds (populated cache) beating GitHub's default cold start (cache disabled) by anywhere from 5x to more than 140x, depending on the project.

PDF Data Extraction in Astera ReportMiner

This video shows how Astera ReportMiner extracts structured data from PDFs in two ways: a reusable template for consistent layouts, and an AI-driven pipeline for documents that vary. Working from a mix of PDFs, digital and scanned, that vary in layout and quality, you can build a custom extraction logic in ReportMiner: Whether a PDF arrives with a known layout or a new one, it runs through the same pipeline into the same output, with fewer manual exceptions and less setup.

Claims Administration: What It Covers and How to Streamline It

In 2026, claims administration connects intake, assessment, reserves, payments, compliance, and performance reporting. It directly affects settlement speed, operating costs, financial accuracy, and customer satisfaction. Insurers need integrated data, automated workflows, and consistent decision controls.

Predictive Analytics in Real Estate: From Historical Reports to Forecasting

The forecasting model is often the smaller part of the job. In production, what makes predictive analytics in real estate reliable is the infrastructure around it: governed historical data, unified business entities, feature pipelines, model serving, monitoring, and integration into the systems where people work.

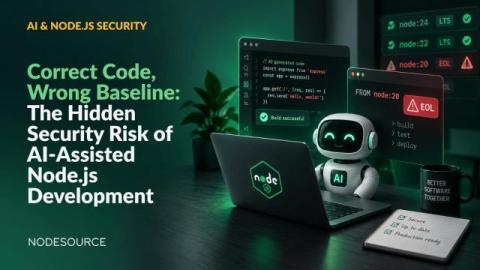
Correct Code, Wrong Baseline: The Hidden Security Risk of AI-Assisted Node.js Development

AI coding tools are becoming increasingly capable of writing software that compiles, passes tests, and solves real engineering problems. But generating working code is only part of what these systems now do. When an AI assistant creates a Node.js project, it may also influence decisions about: Those decisions can survive much longer than the generated code itself.