Systems | Development | Analytics | API | Testing

Five Ways to Use OpenTelemetry Beyond Observability

OpenTelemetry graduated from the CNCF in May 2026 as, in the foundation’s own words, the de facto observability standard. The JavaScript API package alone did 1.36 billion downloads in twelve months. That kind of win has a side effect nobody plans for. Once a wire format is everywhere, has a receiver for every source, a transform language, and an agent your platform team already operates, people start putting things on it that have nothing to do with knowing whether a service is healthy.

Your Observability Stack Found the Fire. Congratulations.

The dashboards are red, the alerts are firing, and Slack has officially become a war room. Someone has asked, “Anyone else seeing this?” and 14 people have immediately responded with screenshots. Welcome to another day in distributed systems. The recent GitHub outage is a great reminder of how complicated modern applications have become. Services talk to services, infrastructure scales up and down, retries multiply traffic, and dependencies behave in ways nobody expected.

Instant Kubernetes Observability with Proxymock #speedscale #kubernetes #ebpf #devops #cloudnative

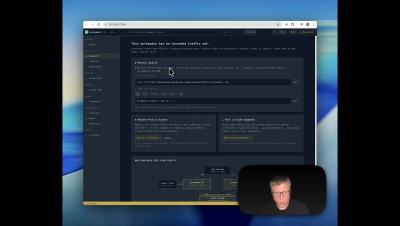
Learn how to get instant observability into your Kubernetes cluster by installing the Speedscale operator and proxymock tool. In this step-by-step tutorial, we walk you through setting up the operator to capture live network traffic (including encrypted traffic, API calls, and database calls) without complex instrumentation or manual configuration.

AI is Exposing Observability's Dirty Secret

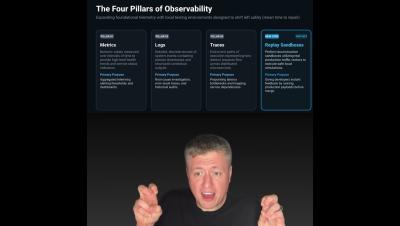
The 3 pillars of observability are breaking. For years, dev teams relied on Logs, Metrics, and Traces to know when something went wrong. But now? AI agents are writing, deploying, and changing code in real-time. When an AI hallucination pushes a bug to production, standard monitoring sees nothing wrong.To survive the AI era, we need a 4th Pillar of Observability. Watch to find out what it is and why the old way of monitoring just became obsolete.

How to curate observability data for AI agents

Most debugging agents fail not because the model is wrong, but because the data going in is not ready for machine consumption. Here's what data curation actually looks like in practice. When we started building Multiplayer's debugging agent, we made the same mistake almost everyone makes. We gave our coding agent access to observability data and expected it to figure out what was relevant. It didn't.
Sponsored Post

The Kubeshark Workflow That Doesn't Stop at the Dashboard

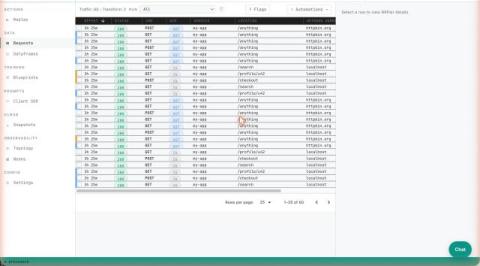
The Observability Gap shows up the moment you try to reproduce a production bug locally. Your traces tell you a request was slow. Your logs tell you which line printed. Neither tells you what was actually on the wire: the headers, the JSON body, the surprise field your client started sending last Tuesday. Until now, closing that gap meant SSHing to a node, attaching a debugger, or shipping a sidecar through change review.

More Signal, Less Guesswork: New Kafka Observability Updates in Confluent Cloud

We’re introducing enhanced visibility for streaming workload performance on Confluent Cloud, making it easier for developers and operators to understand, troubleshoot, and optimize real-time applications. As Apache Kafka has become the backbone of data streaming, many teams rely on Confluent Cloud for its scale, elasticity, and reduced operational burden.

When Your Observability Literally Stops Traffic

Last week, a fleet of autonomous robotaxis in China suddenly stopped working—at scale. Over a hundred vehicles stalled across a city, stranding passengers in traffic and raising immediate concerns about safety, reliability, and trust in autonomous systems. This wasn’t just a bad day for self-driving cars. It was a distributed systems failure, one that happened in the physical world, not just in dashboards.