Systems | Development | Analytics | API | Testing

Reducing GitHub reliability risk for tool installs

You’ve probably encountered the online conversations about GitHub’s AI scaling challenges. A lot of the chatter is about how forgiving (or not) users should be to GitHub in light of inexorable traffic increases but also GitHub’s own decision-making. There is certainly irony in the fact that it was a swashbuckling GitHub, against the objections of many open source developers, that pressed Copilot on the industry.
Ep 95 | AI Agents Move Fast. Can Security Keep Up?

Your AI agent has credentials. Now, what happens when it goes off script? An agent can take action and change course before a traditional security review even begins. For Alex Bovee, identity is only the beginning of the security conversation. In this episode of The AI Forecast, Paul Muller sits down with Alex Bovee, co-founder and CEO of C1 and longtime cybersecurity and identity leader, to explore how autonomous AI agents are changing enterprise security.

Jeff McMillan on How to Think About AI and Jobs

AI and jobs… the topic that’s top of mind for everyone, yet most organizations are asking the wrong questions. The conversation usually starts with cost cutting: how do we reduce headcount, automate repetitive tasks, trim the budget? Jeff McMillan, founder of McMillanAI, thinks that's the wrong frame entirely. He shares what the better questions are in this clip from The Data & AI Chief podcast.

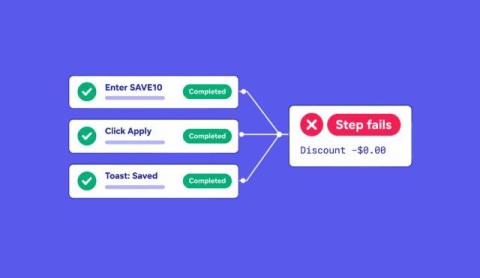
Katalon AI Test Execution and False Passes

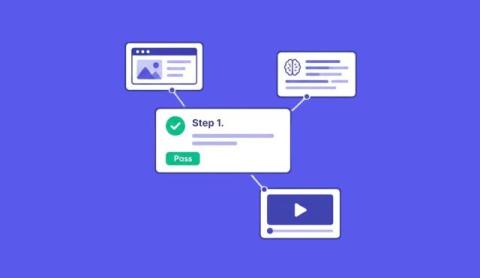
In a release test I published in July, Katalon’s AI runner reported seven cases passed and four failed. I could open the steps, inspect their screenshots, and watch the browser session. The failed rows showed which expectations broke. The passed rows deserve the same scrutiny: what had the agent observed before it called each step passed? An AI test runner has to perform the action and judge the outcome. A false pass is a passed verdict when the expected behavior did not occur.

10 Best Agentic QA Tools in 2026: Compare Workflows, Ownership and Cost

Your team has more changes to test, more environments to cover and less time to maintain regression suites. AI can help produce tests, but that introduces another workload: deciding whether those tests check the right behavior, whether a repair hides a defect and whether the evidence is enough to support a release. Agentic QA tools aim to take on more of that work, from planning and authoring to execution and failure investigation.

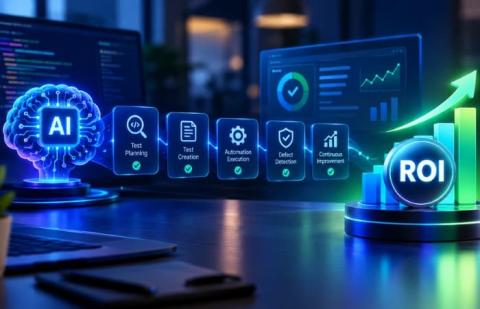
Strategic ROI Frameworks for AI-Driven Quality Engineering

Enterprise software organizations allocate most of their total IT budgets to software validation and quality maintenance. According to the Consortium for Information and Software Quality (CISQ), poor software quality drains over $2.41 trillion annually from the US economy in operational failures, technical debt, and unmitigated production incidents.

Introducing Kong Bot Detector: Native API Bot Detection for Dedicated Cloud Gateways

Bots make up more than a third of internet traffic, and API endpoints attract more of it than web pages do. Scanners hunting for.env files, credential-stuffing scripts, LLM training crawlers, and the long tail of low-effort probes all hit your gateway before they ever reach a service. Every one of those requests costs you — in upstream load, in noise across your analytics, and in the bill.

AI Test Case Generation From Testable Requirements

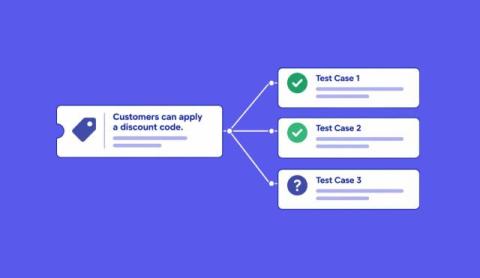
“Customers can apply a discount code” looks ready for testing. Give that sentence to an AI model and it can produce cases for valid, invalid, expired, and reused codes in seconds. The trouble starts when someone asks what a valid code should do. Which basket is eligible? Does the discount change the displayed total before or after tax? Should the saved order carry the same amount?

Katalon AI for Software Testing: Agent Actions and Evidence

In one release test, my AI agent triaged 43 backlog items into 134 executable cases in Katalon True Platform. The first pass at the steps caused trouble. We had bundled setup, navigation, action, and judgment into long instructions. The runner returned verdicts, but a failed step left me unsure which expectation it had checked. We split the cases into one action and one checkable expected result per step. The failures became specific enough to review against the screenshots and session recording.